8 years
Production AI experience across enterprise clients
5 hrs → 40 min
Document search time for a tax firm
2 patents
AI optimization patents registered in South Korea
Recent Work
Case 01
Boditech Med · Translation pipeline
A docx-to-docx translation pipeline I built and run. Tables, numbering, and styles come back where they were instead of collapsing into plain text. Approved terminology is enforced from a glossary, and the terms that must never be translated are locked before the model sees them. Prior approved sentences are reused through a translation memory. Adding a language does not mean rebuilding the pipeline.
Case 02
Corporate training
Eight sessions of hands-on AI engineering training for an in-house committee at a medical device manufacturer, run on their own working problems rather than toy examples. Completed.
Case 03
Gahyun Tax · Document search
A tax practitioner was spending up to five hours hunting through tax code, precedents, and old case files for one answer. That is now under 40 minutes, and the answers are more often right. A retrieval pipeline over the tax code and case files is what made it work; the client only cares that the search stopped eating the day.
Case 04
LG Energy Solution · Multi-agent pipeline
A LangGraph multi-agent pipeline for talent data acquisition across global sources, with Crawl4AI for structured extraction, EXAONE for domain reasoning, and an evaluation framework to keep the output honest. 97% extraction accuracy on the fields it collects.
Live Demos
↗Four working systems you can use right now. Upload one of your own documents to the first three and see what comes back. Validation checks the totals. It’s the same reconciliation listed in the packages below.
Document Q&A ↗
Upload a PDF and ask it questions, back and forth, without reading the whole thing yourself.
Document Extraction ↗
Upload a PDF and get the fields back as structured JSON instead of retyping them.
Document Validation ↗
Upload a spreadsheet or PDF and it checks whether the tables actually add up. Every mismatch comes back with the cell it sits in, the value the document should show, and the value it does show.
Ask Hannune ↗
A multi-turn assistant that answers questions about Hannune from a structured profile.
Free document tools
PDF convert, split, merge, compress, background removal, table total check. No signup needed for the basics.
Open toolsServices and Products
01 · Service
Available nowAI Agent Automation
An AI agent that takes over a repetitive workflow a company still runs by hand, often one built around mixed Korean, Japanese, Chinese, and English documents and vendor data. Document translation, extraction, and review are one workflow the agent handles: the file comes back looking like the file you sent, and the figures it pulls out are checked against each other before you see them. Fixed scope, fixed price, fixed timeline.
See packages ↓02 · Product
Available nowEntity Resolution API
Entity Resolution as a service. Deduplication and entity linking across datasets — built on Splink with an LLM disambiguation layer. No self-hosting required. Free tier, then from $19/mo.
See pricing and start free → Ask about a custom plan →03 · Showcase
Live now2asy.ai
Northeast Asia (Korea, Japan, China, Hong Kong) risk and compliance intelligence, and a live showcase of the same agent technology rather than a product for sale. It reads economic and regulatory disclosures daily, extracts causal relationships, and publishes structured analyses on its own, pointed at public filings instead of a client's files.
Visit 2asy.ai →01 · Service Available now
AI Agent Automation
An agent takes over one repetitive workflow: reading mixed-language documents and vendor data, translating and extracting what matters, and checking that the figures actually add up before anyone reads them. Most tools translate a document well and hand it back with the table broken and the columns collapsed. Most extraction tools pull numbers out and never ask whether the line items add up to the total on the summary page. Fixed scope, fixed price, fixed timeline, and you deal with the engineer who builds it. Your data stays wherever you decide, in your cloud account or on your own servers.
Package 01 · Validate
Pilot
One workflow, run end to end on your real data, measured before and after.
$1,500 fixed
Fixed scope · one workflow
- ScopeOne workflow: your real documents and data in, measured results out
- FitsMixed-language document translation · extraction · vendor data workflows
- OutputWorking agent + a before/after accuracy report on your own data
- Incl.A straight answer on what is worth automating next
- CreditPilot fee credited to Setup if you sign within 30 days
- RefundRefund within 30 days if the agreed metric is missed
Package 02 · Build
Setup
The agent connected to your systems and kept running on its own.
From $5,000
Fixed scope · connects to your systems
- ScopeAgent connected to your mailbox, CRM, or document store, running continuously
- ChecksTerminology rules, do-not-translate lists, totals reconciled across sections
- OutputProduction agent + handoff
- Incl.Full codebase transfer + docs + training
- SLAResponse within 2 business days
Package 03 · Scale
Enterprise
Several workflows, several teams, inside your own infrastructure.
Contact for pricing
Scope and pricing agreed after a scoping call
12+ weeks · Custom scope
- ScopeAgent workflows across teams, plus search and review on top of them
- RunsYour cloud account, your own servers, or fully air-gapped — your call
- OutputFull system + 3 months on-call support
- Incl.Retrieval and agent layers where they earn their keep · custom model tuning
- SLADedicated support
Add-on · Ongoing
Retainer
Keep the agent accurate as your workflow changes.
Available after any completed package. Includes a monthly accuracy check, small adjustments, and one new document type or language added per month.
$1,000 /mo
Min. 3 months
Custom engagements
Retainer-only arrangements, training programs, or scope beyond the three packages. We reply within 2 business days.
Long Documents, Read Properly
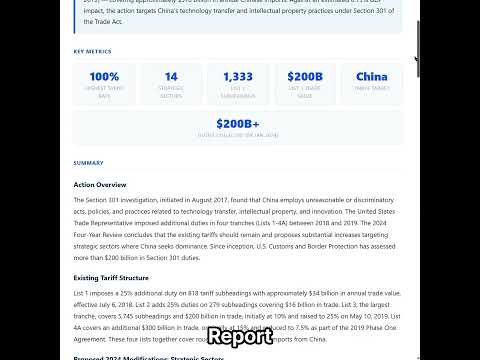
Three public documents nobody wants to read end to end: a 418-page competition ruling, a 187-page trade review, and an SEC annual filing. Each one was put through the same pipeline and came out as something you can actually follow. Knowledge-graph retrieval sits underneath, which matters to me and not to you.
 Corporate
60s
NVIDIA 10-K FY2026
Knowledge graph extraction from NVIDIA's SEC 10-K filing using iXBRL parsing.
View →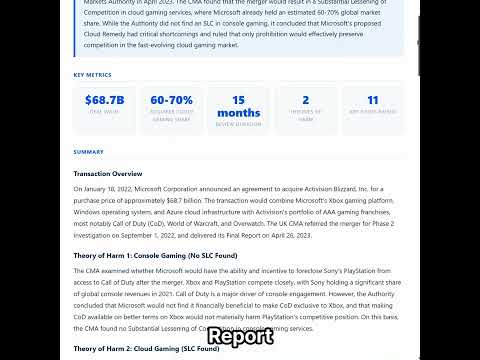 M&A
60s
Microsoft–Activision: CMA Final Report
How the UK CMA blocked Microsoft's $68.7B Activision acquisition, mapped from the 418-page final report.
View →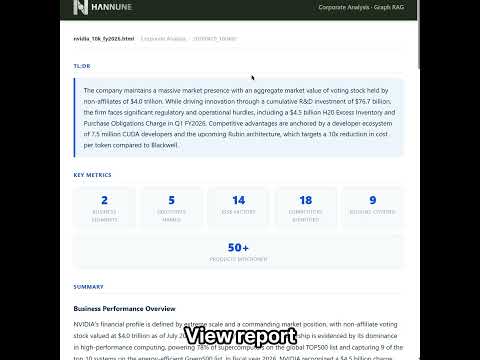 Trade Policy
60s
USTR Section 301: 2024 Four-Year Review
US tariff policy on Chinese imports analyzed from the USTR's 187-page review, including 2024 proposed increases.
View →What I Build
The document work an agent handles most often, and the technology I reach for underneath it.
The document work
The two hard parts
Underneath, when it earns it
2asy.ai: Northeast Asia Risk and Compliance Intelligence
The same document machinery, pointed at public filings instead of a client's files, and left to run on its own. Every day it reads economic and regulatory disclosures across Korea, Japan, China, and Hong Kong, pulls out the causal relationships, and publishes structured analyses.
It happens to be tracking oil, energy, and geopolitics. The pipeline does not care about the subject; point it at a different pile of documents and it works the same way.

- ~2,400 articles ingested daily
- ~100 articles selected for knowledge graph
- Causal graph visualization on every edition
- Runs on Neo4j + LangGraph + Ghost CMS
Identity
One person, accountable from the first conversation to the system running in production. No account manager in between.
- Build and deliver the system end to end
- Own the architecture, the code, and the deployment directly
- Contract work for companies and professional firms
- Solo by design — one person to ask, one person to blame
Operating Model
One technical owner from system design to deployment, with no handoff gaps between planning, implementation, and operation.
Fit
This works best when there is a real repetitive workflow and a real person losing hours to it.
When this is a good fit
Your workflow runs on documents with structure worth keeping, tables, columns, numbered sections, house terminology, often in more than one language, and the off-the-shelf tools keep wrecking it. Or you are pulling figures out by hand because nobody trusts an extraction they cannot check. Or the same task happens every week and someone is doing it by hand.
When this may not be a fit
A handful of plain documents a month that ChatGPT already handles fine. Research projects with no workflow behind them. And anything where nobody has actually looked at what the current process costs.
Get In Touch
Send me a document or describe the workflow your current tools handle badly, and tell me what it should have looked like. That is usually enough for me to say whether this is worth your money.